



When someone asks me about HAProxy alternatives, my first question back is always the same: what do you actually need to change? Simpler HTTP configuration, container discovery, a managed cloud entry point and global origin steering are four different problems.
This shortlist covers twelve real projects and services. Not all are drop-in replacements, and none wins every workload. Pick the category first, then the product.
New to the terminology? Read what a load balancer does first.
Quick selection mapSelf-hosted open sourceManaged and commercialChoose the category firstMigration planFailure and securityFAQs
Start here The quick selection map
The whole list in one view.
| Option | Starting scenario |
|---|---|
| NGINX Open Source | Existing NGINX web stacks |
| Envoy | Service-oriented environments |
| Traefik Proxy | Container-oriented routing |
| Caddy | Simple web proxy setups |
| Apache HTTP Server | Teams already running Apache |
| Apache Traffic Server | Cache-heavy proxy delivery |
| AWS Elastic Load Balancing | Applications hosted in AWS |
| Google Cloud Load Balancing | Google Cloud workloads |
| Azure Application Gateway | Regional HTTP routing in Azure |
| Cloudflare Load Balancing | Multi-origin edge steering |
| DigitalOcean Load Balancers | DigitalOcean deployments |
| F5 BIG-IP | Enterprise application delivery |
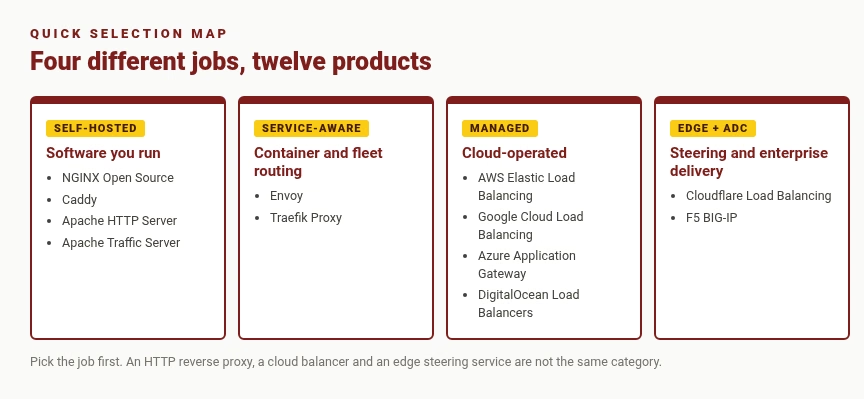
Need a narrower edge comparison? The Azure Front Door vs CloudFront comparison covers two-origin web delivery and edge caching. Neither edge product is a generic TCP proxy replacement.
Part one Self-hosted open source options
These six run on your own machines or VMs. You own configuration, upgrades and on-call. If that operating model does not fit your team, skip ahead to the managed group, or read how to choose the right tech stack for your business first.
NGINX works as an HTTP reverse proxy and spreads traffic across an upstream group. Its documentation covers round robin, weights, least connections, IP hash and generic hashing. It also proxies TCP and UDP through its stream module.
That makes it a strong candidate when your team already knows NGINX and wants web serving and upstream routing in one stack. New to the vocabulary? My guide to what a load balancer does covers it in plain English. Keep Open Source and NGINX Plus separate in your head: the primary HTTP guide marks features like sticky-session methods as edition-specific. Check your exact build instead of importing an old feature chart.
For a HAProxy migration, inventory your ACLs, headers and timeout rules and translate them deliberately. An NGINX config is not a drop-in parser for HAProxy config, so test client IP handling and backend-change behavior before you commit.
Envoy is an open-source edge and service proxy. Its upstream load-balancing docs describe round robin, least request, random, ring hash and Maglev. It is a candidate when routing is part of a broader service architecture rather than a standalone web server.
A data-plane proxy still needs configuration ownership. If you use a control plane, review how it publishes endpoints and reacts to failure. Installing Envoy alone does not create service discovery, a management UI or a complete service mesh.
For migration, reproduce one listener and backend cluster first, then compare headers, timeouts and error behavior. This fits teams already thinking in multi-cloud infrastructure terms. The real cost is managing the surrounding design, not the software license.
Traefik Proxy presents itself as a cloud-native application proxy with service discovery, routing and load balancing. Its service docs describe backend server lists and service-level traffic handling.
It is worth a look when changing application instances should feed routing through the platform instead of hand-edited static files. Discovery reduces manual endpoint work, but you still review provider permissions, network exposure and routing labels. A dashboard is not a substitute for access controls.
A migration should map entry points, routers, middleware and services to the old configuration’s responsibilities. Keep the trial small and observable, the same way I treat other efficiency tools that change a workflow: prove one service, then expand.
Caddy is a web server with a configurable reverse_proxy directive. Its directive reference documents upstream selection, load balancing, and active and passive health checks. For a small web stack where readable configuration and certificate handling matter, it is a genuinely pleasant option.
Caddy is not a generic replacement for every transport-layer feature. Check protocol requirements and modules before assuming a standard install covers a specialized HAProxy deployment. The reverse-proxy guide also documents conditions for active health checks and dynamic upstreams that deserve a careful read.
Test the real application: redirects, forwarded headers, streaming and retries. A shorter config is easier to maintain, but correctness still depends on timeout choices, eligible upstreams and a safe deployment process. Choosing it is a stack decision as much as a proxy decision, so run it through the same filter as choosing the right tech stack for anything else.
Apache HTTP Server can proxy to backend pools through mod_proxy_balancer. The module docs describe balancer workers and the algorithms its companion load-balancing modules supply. When Apache is already your front-end server, this is the path of least surprise.
The required modules must be enabled and configured together. The existence of mod_proxy_balancer is not a complete default health-check policy or a secured management endpoint. Review the related proxy, protocol and scheduler modules in your own distribution.
Use a small staged backend group and confirm routing, affinity and failure handling. The tradeoff: configuration still needs active maintenance, and a single Apache host stays a single failure point. If your traffic also carries sensitive records, keep data governance basics in scope while you rewire the entry point.
Apache Traffic Server is a caching proxy that can work as a reverse proxy and Layer 7 HTTP load balancer. Its docs describe next-hop selection by request attributes, with strategies like weighted round robin and URL consistent hashing. Pick it when cache behavior is a major part of the job.
It is a different starting point from a general TCP/HTTP balancer. TLS tunneling and SNI routing are documented separately from cached HTTP delivery, and tunneled traffic cannot be cached as an HTTP object on that path.
Choose it because you need its proxy and cache architecture, not because every proxy is interchangeable. Plan cache keys, origin headers, invalidation and next-hop policy together, and treat cache warming like any other automation you verify before relying on it. Check the maintained release and security notices before deployment.
Part two Managed and commercial services
The next six trade proxy-host maintenance for platform dependency and usage-based cost. You still own application health, permission boundaries and the bill. If that trade is new territory for your team, an outside review from IT architecture consulting firms can sanity-check the design before you commit.
Elastic Load Balancing is a managed service family. The Application Load Balancer guide describes HTTP-aware listeners, rules, target groups and target health checks. Network Load Balancer is a separate choice for different transport requirements.
Choose the specific balancer type before comparing features. An ALB is not an interchangeable raw-UDP proxy, and managed infrastructure does not fix application-state consistency, target permissions or a failed shared database. Provider quotas and billable usage need review for the service you pick.
Migrating from HAProxy changes the configuration model and the operating boundary. Translate routes and health checks into listeners and target groups, and validate security groups, TLS termination and how your logs record the client address. When the AWS side of the design grows, cloud consulting partners are a reasonable shortcut for the first review.
Google Cloud offers application and network load-balancing families with regional or global, external or internal designs. Its overview distinguishes proxy-based and pass-through choices. It fits workloads that already live on Google Cloud.
Do not describe the whole family as one protocol and feature set. Select the exact service, scope and backend support from the current decision guide. A global application balancer and a regional network balancer have different jobs and constraints.
Map the traffic path and backend placement before migrating. Review certificates, health checks, firewall rules and how the chosen balancer exposes metrics. Keep platform dependency and usage-based cost visible in the selection, and revisit the design as your multi-cloud footprint changes.
Azure Application Gateway routes web traffic using HTTP attributes like URL paths and host headers. Its overview lists TLS handling, cookie-based affinity and optional WAF integration. It fits an Azure web app that needs application-aware routing inside a region.
It is not Azure Load Balancer, which is a Layer 4 TCP/UDP service. It is also not the same global edge-delivery product as Front Door. Review the exact tier, deployment model and features instead of treating every Azure networking name as equivalent.
A migration should preserve path routing, certificate boundaries and backend health settings. Review affinity if the application keeps local state. Model failover for the backend and its data dependencies separately from gateway availability. When the routing gets complex, experienced cloud consulting partners can pressure-test the design.
Cloudflare Load Balancing documents pools, endpoints and monitors that steer traffic across origins, including environments spread across providers. It is an edge or DNS steering choice, not software you install in place of a local HAProxy process.
Review proxied versus DNS-only behavior, steering policies and your plan level. DNS changes are affected by caching, while a proxied path introduces its own HTTP behavior. Do not promise identical failover timing or transport support across those modes.
Check origin protection as part of migration: if users can bypass the edge and reach an origin directly, your traffic policy may not hold. For a head-to-head on the two big edge platforms, see my Front Door vs CloudFront breakdown.
DigitalOcean documents load-balancer products for its platform. The regional service includes backend health checks, TLS termination and sticky sessions. It is a candidate when your application already runs on DigitalOcean infrastructure.
The current feature guide explicitly says standard HTTP balancing does not route to specific backends by URL, cookie or HTTP header. Verify the regional or global product, supported protocols and backend restrictions before committing. The managed service operates the balancer, but you still need suitable replicas and secure network rules.
For migration, check how targets are selected and how health settings map to your application. Confirm certificate behavior, session affinity and logging, and count the cost of moving backends, not just the balancer’s price. Teams without in-house ops depth sometimes pair this move with DevOps consulting help.
F5 sells application-delivery and load-balancing products, including BIG-IP. This is the candidate when application delivery is part of a larger enterprise environment with established support, policy and operational requirements.
BIG-IP is a product family with deployment and licensing choices, not a universal free-software substitute. Get the exact edition and module requirements from F5 for your target environment. Do not infer a WAF, every protocol feature or an entitlement from the family landing page.
A migration needs a feature-level inventory and an ownership plan. Have the supplier walk through your routing and failure scenarios; procurement and skills matter as much as traffic policy, so big buyers bring in architecture consultants for the evaluation.
Decision guide Choose the category before the product
Small apps or changing fleets
For a small app, compare readable config, certificates, backend checks and who answers the 2 AM page; Caddy, NGINX and Apache are safe starts when the team knows them.
For changing fleets, judge Envoy and Traefik with their control-plane setup, not as isolated binaries. Product-focused teams often hand this whole layer to a DevOps partner.
Cloud workloads and cache-heavy tiers
On a major cloud platform, the managed service removes proxy-host maintenance; you still own app health, permissions and cost. When caching is central, Traffic Server or an edge design beats a connection-only balancer.
Feature limits worth a proof check
First, write down whether you distribute connections, HTTP requests, or public objects and origins. Then check these four limits on staging, not on a feature page, with the same skepticism you would give any tool promising efficiency gains.
| Requirement | What to verify | Why it matters |
|---|---|---|
| Raw TCP / UDP | Exact protocol and balancer type | HTTP routers are not transport balancers. |
| Active health checks | Edition, probe conditions, interval, failure policy | Passive failures are a different model. |
| Sticky sessions | Affinity key, lifetime and failure behavior | Local state can vanish with the backend. |
| Dynamic backends | Discovery source, permissions, refresh behavior | A proxy is not a whole control plane. |
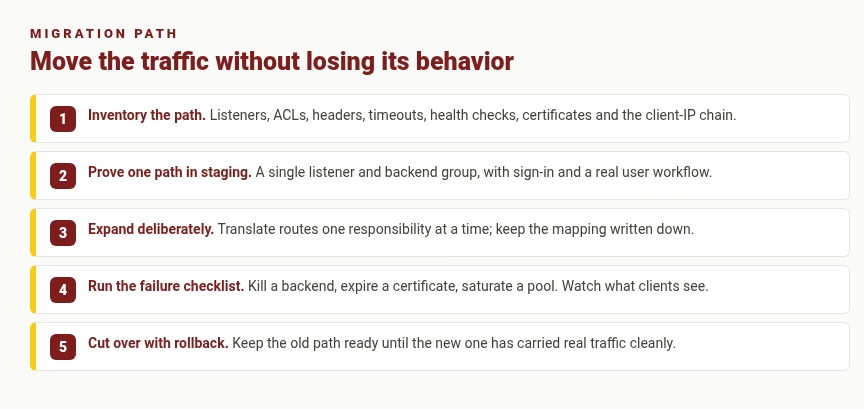
Rollout A migration plan that protects the behavior you rely on
Every balancer migration I have seen fail went wrong the same way: somebody treated a feature label as a guarantee. The path below is boring discipline over heroics, the same lesson as choosing between incremental and differential backups.
Inventory the current traffic path
Write down listeners, certificates, HTTP routes, headers, protocols, timeouts, affinity and health criteria. Include the normal traffic mix and long-lived connections. That inventory is your acceptance checklist for any replacement.
A vendor label like “health checks” is too broad until it matches your probe endpoint, threshold and response conditions. Protect the inventory itself, because the old config is your rollback asset if the new path misbehaves.
Prove one path, then expand
Move a representative low-risk path in staging first. Compare successful requests, errors, redirects, client IP logging and backend changes. Test a controlled failure and a rollback.
Do not move every public route before learning whether retries or affinity change application correctness. Preserve the old configuration, decide exactly how the public endpoint can return to it, and keep that rollback path tested the way you would test a backup restore.
Before production Test failure and security before production
Create a controlled failure checklist
Remove one backend, make another slow, and fail a dependency separately. Watch new and existing connections, timeouts and retries. A green backend check does not prove login, checkout or writes are correct.
In particular, make writes safe against duplicate execution before allowing broad retry behavior. Record recovery observations with the same representative traffic for each candidate.
Protect the public endpoint and the origins
Restrict origin access where the design allows it, and define which proxy may supply trusted client-IP headers. Keep TLS certificates and origin verification in the plan. Secure management interfaces and discovery credentials.
A protected edge with an openly reachable origin leaves a bypass path. Revisit these rules when backends, cloud regions or the proxy operating model change, and fold them into your broader data governance habits so the next migration starts from documentation, not memory.
Answers Frequently asked questions
Which is the best HAProxy alternative?
There is no universal winner on this page. Select by traffic protocol, backend location, operating skills and required failure behavior. An HTTP reverse proxy, a cloud application balancer and an edge steering service are different categories. Use the shortlist to pick a small set, then run the same staging acceptance checks on each.
Can I replace HAProxy without rewriting its configuration?
Do not assume it. Different products use different listener, route, health and timeout models, so migration means translating behavior and verifying the application. For operating cost, count hosting, updates, redundancy and on-call ownership as well as provider charges. A lower license cost does not establish a lower total cost or a safer deployment.
Is NGINX Open Source the same as NGINX Plus?
No. They share an ecosystem, but the current primary guide distinguishes edition-specific capabilities such as Plus session-persistence methods. Check the exact feature and version you need, including health checks and runtime management. Old comparison tables go stale quickly, especially as multi-cloud infrastructure keeps shifting, so I link the official project pages rather than promising every feature is in every build.
Can Cloudflare replace a local TCP load balancer?
Do not treat the web origin-steering service as a generic raw-TCP replacement. Review the exact Cloudflare service, mode and protocol requirements, since DNS-only and proxied choices behave differently. For a local transport workload, start with a product that documents the required TCP or UDP behavior and test the connection path end to end.
Do managed services remove the need for health checks?
No. Provider-operated infrastructure still needs a way to decide whether your backends can receive work. Configure a meaningful probe and test its thresholds; a managed balancer cannot infer that a login flow or write operation is correct from an open socket. Your team remains responsible for suitable backend instances and dependencies, the same ownership mindset behind picking automation tools for the rest of the business.
Should I change the balancer to fix slow database queries?
Not as the first remedy. If all backends wait on the same slow database, distributing requests does not remove that bottleneck. Measure where latency occurs and whether the application tier is actually saturated. The fix may be queries, indexes, cache design or database capacity, and a balancer only helps when there is useful capacity to distribute work to.
How do I avoid session loss during migration?
Identify where session data lives, how the current affinity key works and what happens when the chosen backend disappears. Shared state can reduce the need for affinity, but it must be reliable itself. Test sign-in and a real user workflow across a backend change, and keep rollback available until the new path proves correct, including certificate and hostname behavior. Building a new product alongside? Our app builder collection shows how we approach shipping software in general.






Leave a Reply